2 November 2026 · Evaluation
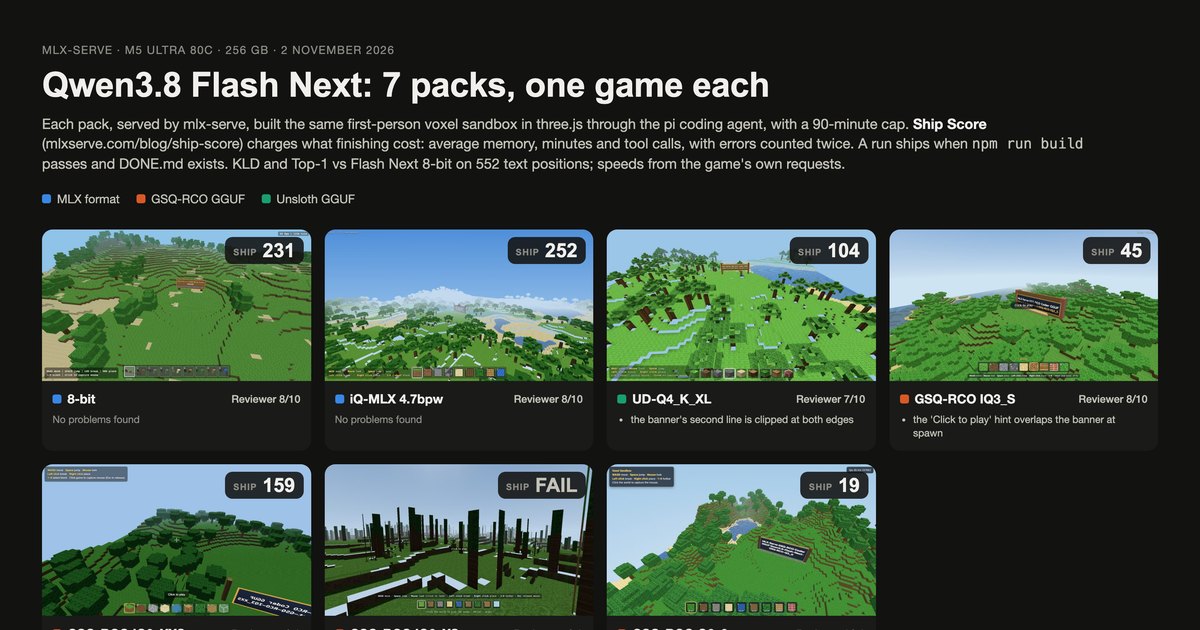
Ship Score: an eval that can't saturate
Give a model one real job and score what it cost to finish: memory, minutes and tool calls. Seven pinned prompts rated 1 to 5, and our first runs on Qwen3.8 Flash Next and DeepSeek-V4.1 Flash.
22 September 2026 · Release 26.9.5
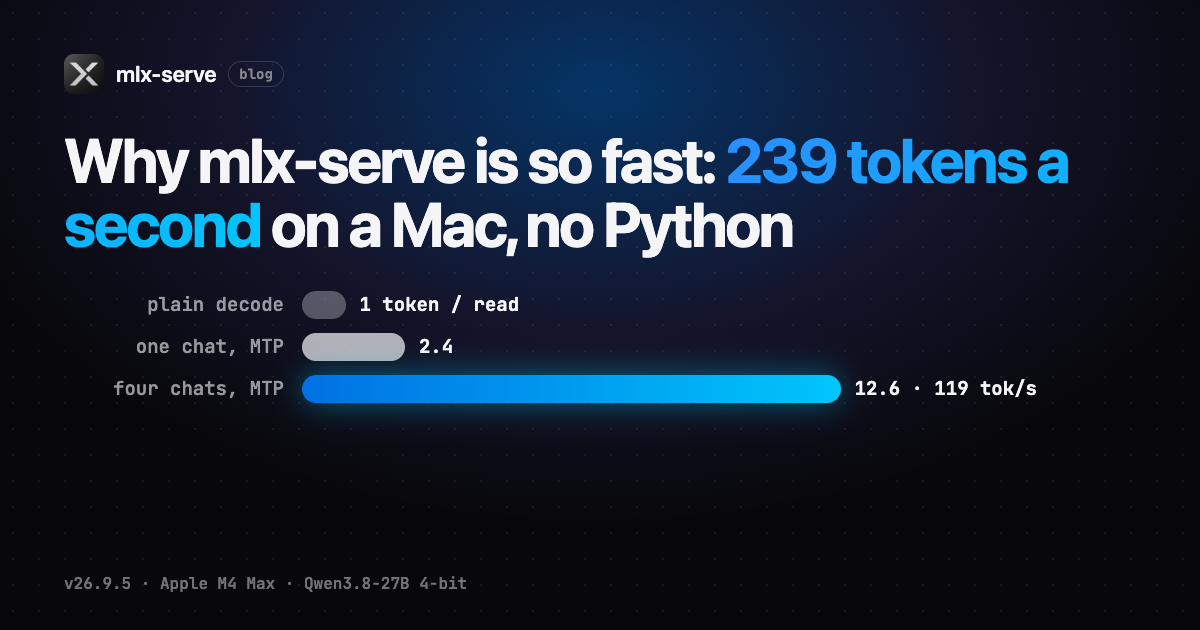
Why mlx-serve is so fast: 239 tokens a second on a Mac, no Python
Four 27B chats at 119 tokens a second combined, 56 ms to the first token on a continued chat, and 8-bit KV as fast as bf16 at 32k. What the engine does with each read of the weights.